UltraWorld: Learning Interactive Ultrasound World Models from Untracked Videos via Acoustic Sampling Map

Anonymous Authors

Anonymous submission to ICLR 2027

Slide
Rock
Depth adjustment
Sweep

Ultrasound futures predicted by UltraWorld from an initial observation and a sequence of scanning actions.

Abstract

World models can enable autonomous ultrasound scanning by predicting the outcomes of probe motions from local observations. Learning this action–observation relationship typically relies on synchronized video–pose pairs, which are costly to collect at scale and largely unavailable in routine clinical recordings. Reliable action following further requires modeling ultrasound’s cross-sectional sampling geometry.

We present UltraWorld, a self-distillation recipe that transfers priors from clinical ultrasound videos into interactive world models without real action annotations. Starting from clinical videos, we adapt a video foundation model into an ultrasound generator conditioned on reference images and anatomical masks. Anatomical masks sampled along programmable trajectories through 3D anatomy provide spatial guidance for synthesizing action–video pairs. We then use these synthetic pairs to self-distill the generator into a world model that predicts future observations from local observations and actions, without requiring anatomical masks or other 3D assets at inference time. To further improve action following, we introduce the Acoustic Sampling Map (AsMap), which represents probe poses and imaging settings as pixel-wise 3D sampling positions, beam directions, and depths.

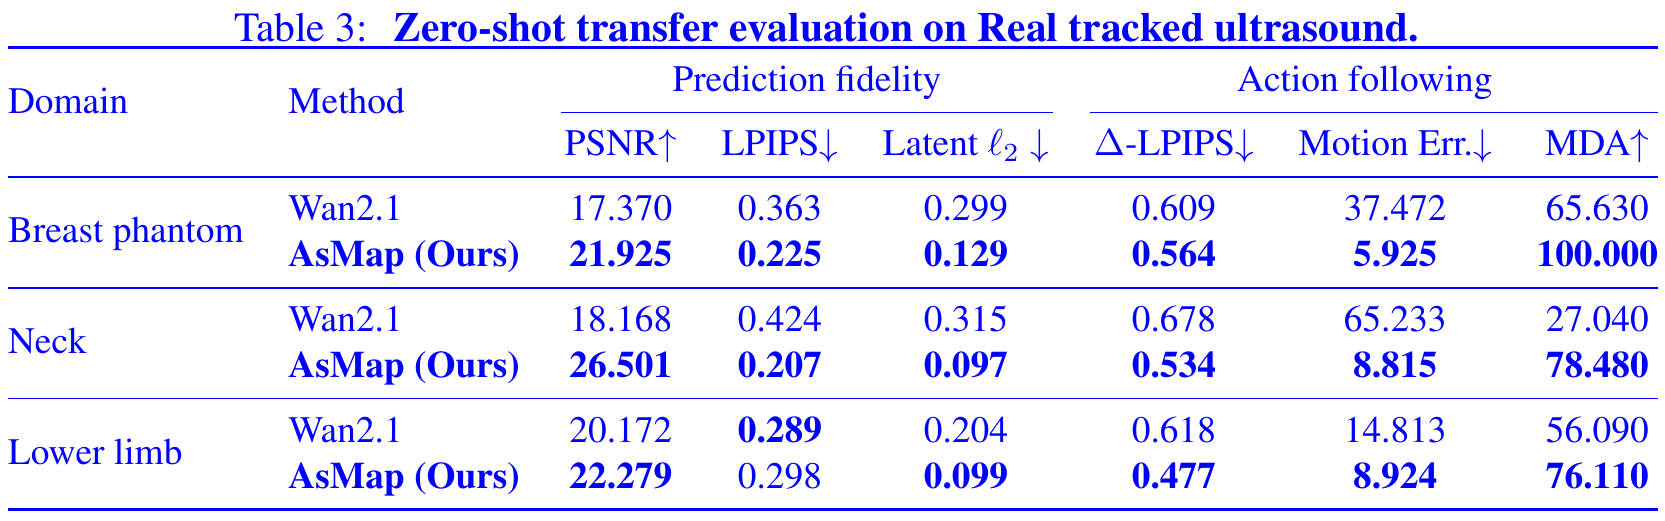
Zero-shot evaluation on real tracked ultrasound scans demonstrates the effectiveness of UltraWorld, reducing Motion Error by 39.8–86.5% and improving Motion Direction Agreement by 20.0–51.4 percentage points over the unadapted Wan2.1 baseline, without training on real video–pose pairs. We further demonstrate closed-loop robotic ultrasound planning in simulation across 24 tasks, achieving a mean final position error of 4.84 mm, a 47.1% reduction over the strongest baseline.

Code: https://github.com/sephohi/UltraWorld.

Overview

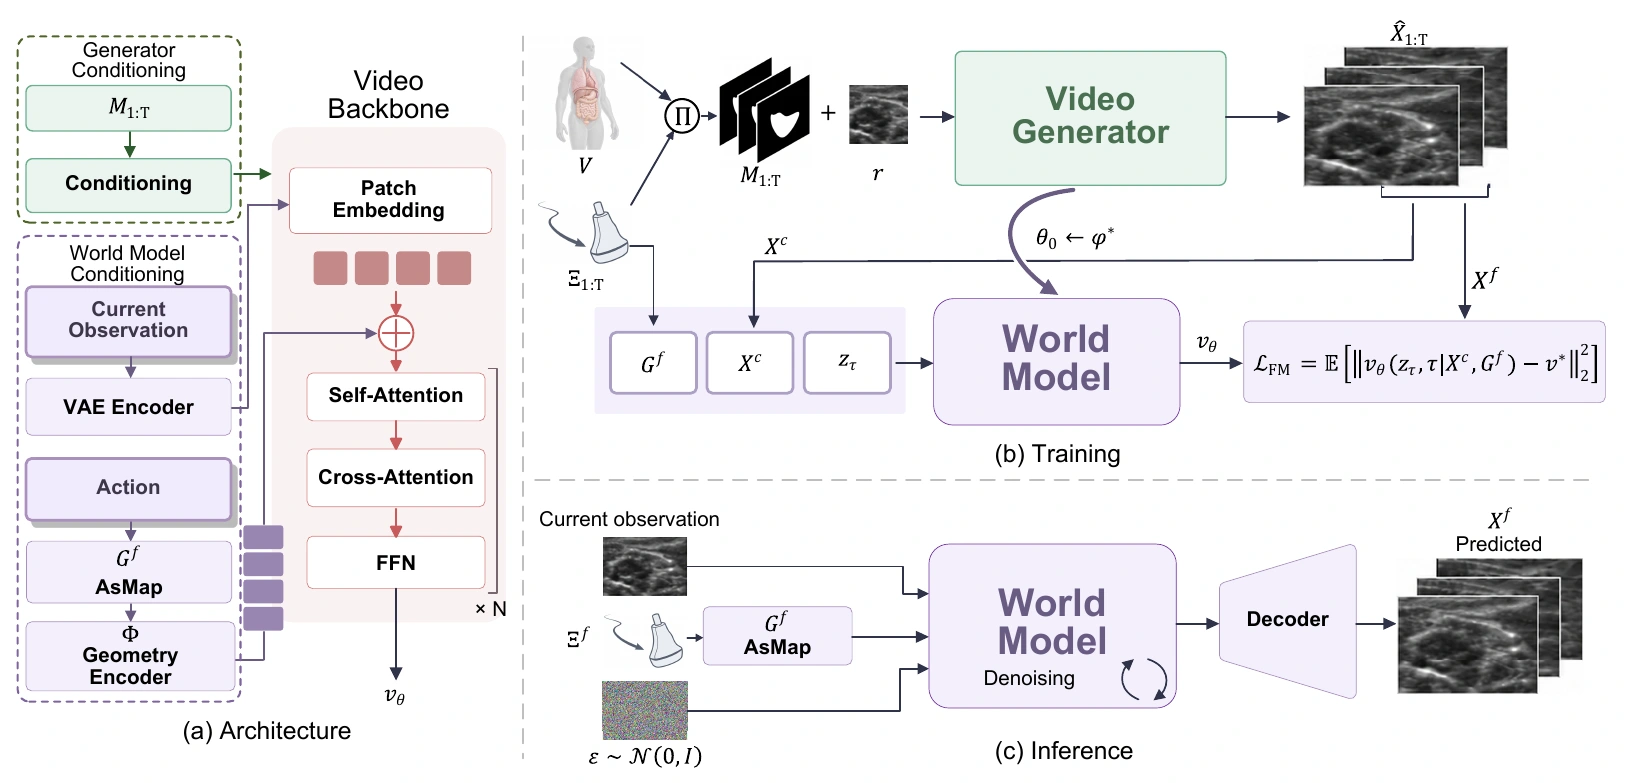
Figure 2: UltraWorld framework
Learning interactive ultrasound world models without tracked clinical scans. Routine clinical videos lack the synchronized probe poses needed for action supervision. UltraWorld learns visual and temporal priors from these videos, then uses anatomical masks sampled along programmable trajectories through 3D anatomy to synthesize action–video pairs. A shared video backbone transfers these priors to an AsMap-conditioned world model through self-distillation. The resulting model predicts future ultrasound observations from the current observation and prescribed scanning actions, without anatomical masks or 3D assets at inference.

Acoustic Sampling Map

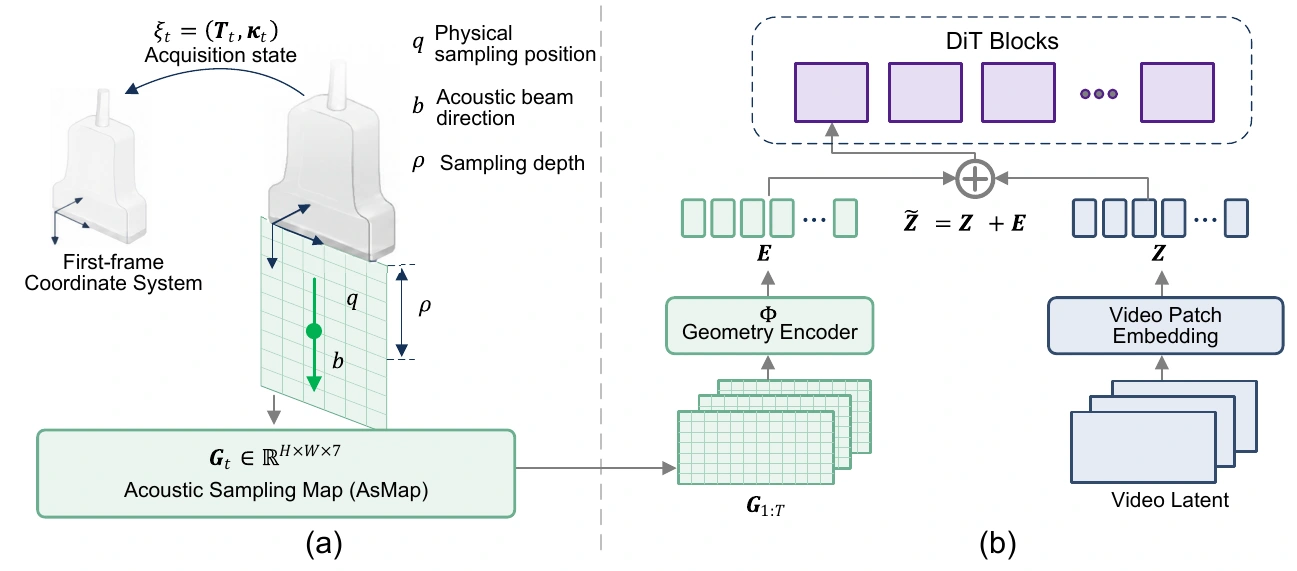
Figure 3: Acoustic Sampling Map
Acquisition-geometric parameterization. AsMap resolves pose-only under-specification by jointly parameterizing probe pose Tt and intrinsic acquisition parameters κt as a seven-channel, first-frame-relative sampling field, injected through token-aligned additive conditioning.
How scanning actions change the sampled anatomy. The animation pairs the probe and B-mode cross-section with maps of sampling position, beam direction, and depth. AsMap makes the spatial effects of probe motion and imaging-depth adjustments explicit at each pixel, including sampling changes that can occur without a change in probe pose. This gives the world model geometric conditioning for predicting how ultrasound observations respond to scanning actions.

Self-distillation

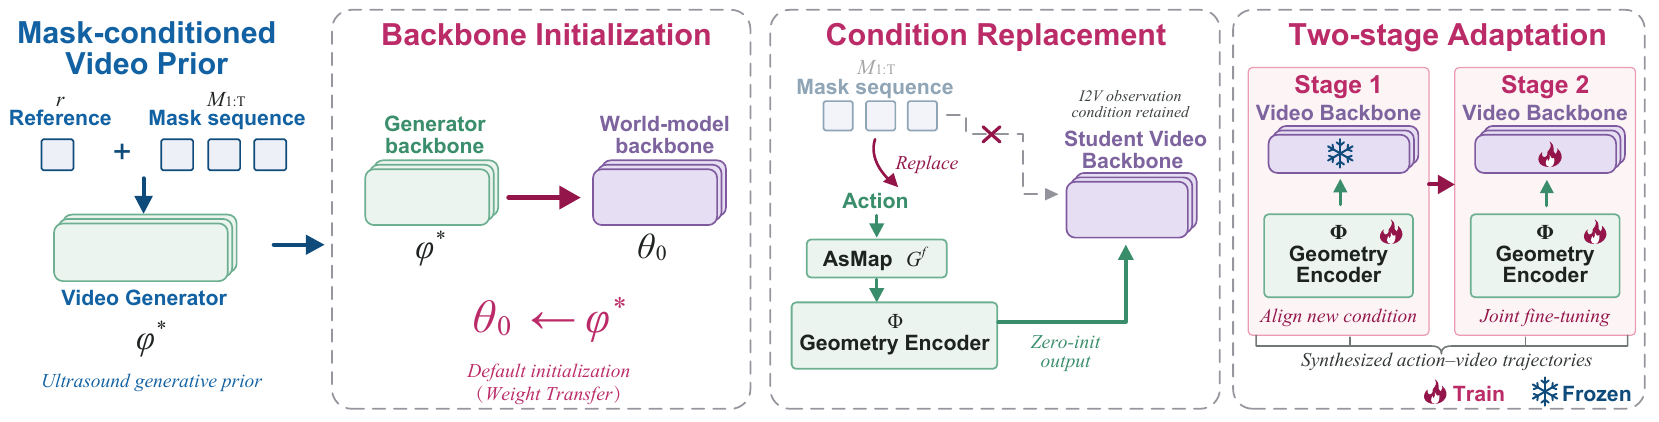
Figure 4: Backbone initialization, condition replacement, and two-stage adaptation
Self-distillation for ultrasound world modeling. The default training procedure consists of three steps: (1) Backbone initialization: initialize the world model from the learned video generator; (2) Condition replacement: replace anatomical-mask conditioning with AsMap conditioning while retaining the observation input; (3) Two-stage adaptation: train the geometry encoder with a frozen video backbone, then jointly fine-tune both. Both stages use synthesized action–video trajectories.

Experiments

Prediction on Synthetic Scans

Slide

Rock

Sweep

Depth adjustment

Revisit

Zero-shot Transfer to Real Scans

Sweep

Limb
Neck
Neck
Limb
Limb

Revisit

Breast phantom

Slide

Neck
Breast phantom
Breast phantom

Quantitative comparisons

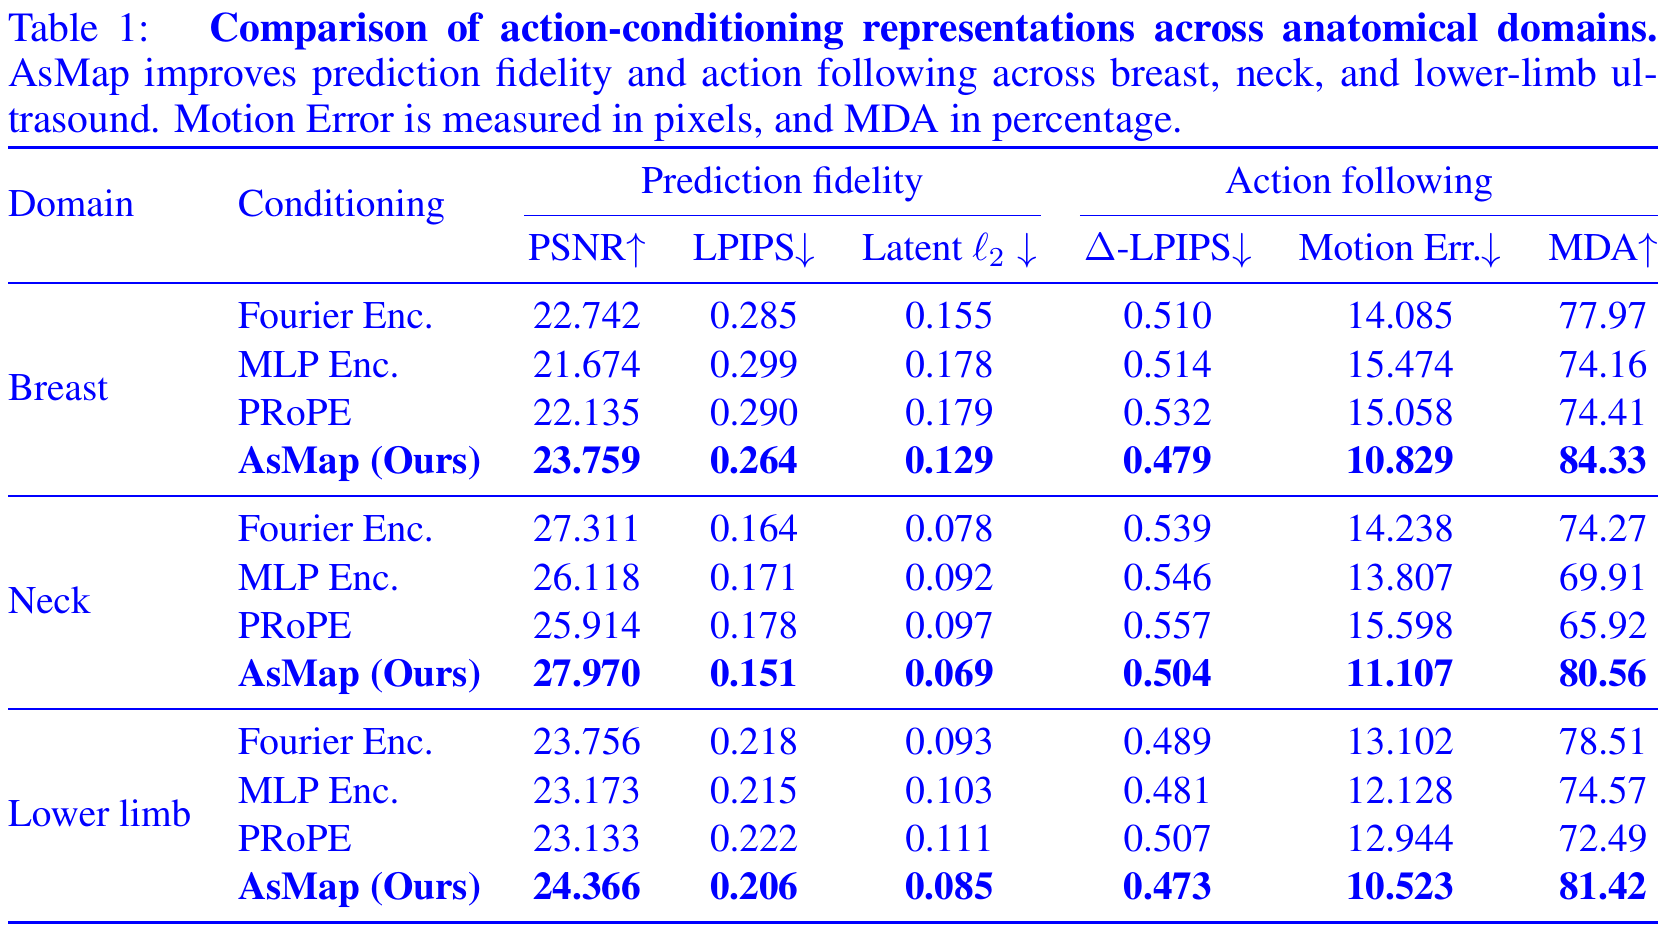
Table 1: Prediction fidelity and action-following results for Fourier Enc., MLP Enc., PRoPE, and AsMap across breast, neck, and lower-limb ultrasound
Table 3: Zero-shot comparison of Wan2.1 and AsMap on breast phantom, neck, and lower-limb scans

Analysis

Long-Horizon Prediction

Synthetic scans

Slide · Limb
Rock · Limb
Sweep · Neck
Fan · Neck
Rotation · Breast

Real scans

Slide · Neck
Rock · Breast phantom
Rock · Neck
Fan · Neck
Fan · Neck
Fan · Neck
Revisit · Breast phantom
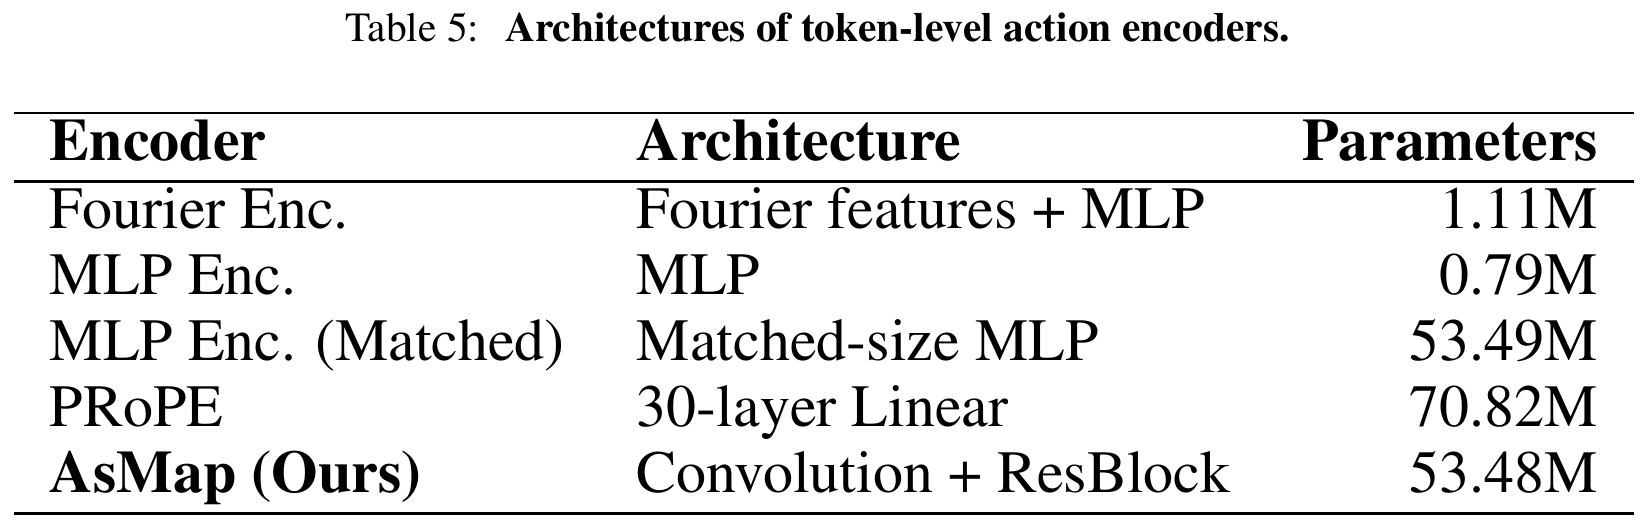
Table 5: Architectures and parameter counts of Fourier Enc., MLP Enc., matched MLP Enc., PRoPE, and AsMap action encoders

Applications

Robotic Ultrasound Planning
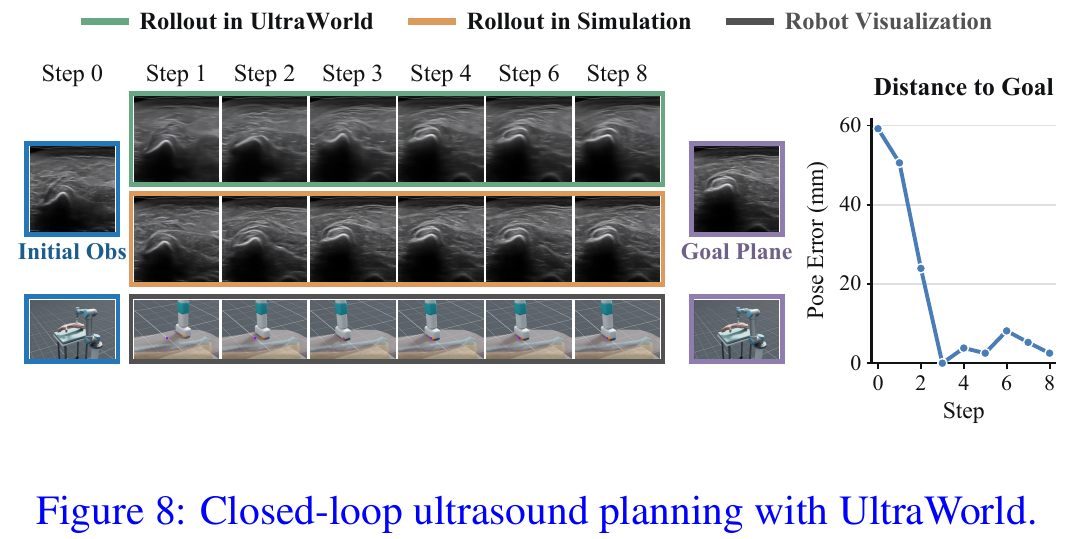
Goal-directed planning in lower-limb ultrasound. Each second shows one executed command; stopped methods hold their final observation.
Figure 8: Model rollouts, simulation observations, robot poses, and distance to the goal during closed-loop ultrasound planning